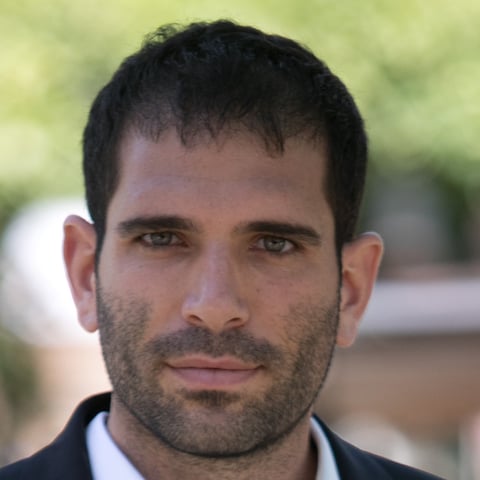
I co-lead the Discovery team at Google DeepMind in London, where I've worked since 2019. My research is on reinforcement learning for hard reasoning and long-horizon planning — mathematics, chess, and origami design, where a solution takes many steps to find and a single wrong step breaks it. A few highlights are below.
Featured Projects
AlphaProof
An AI system that taught itself to prove mathematical theorems in Lean, reaching silver-medal performance at the International Mathematical Olympiad through continuous reinforcement learning.
Read more →COrigami
Combines reinforcement learning with Gemini to design origami crease patterns, using a semantic representation and visual feedback loop to fold arbitrary target shapes.
Read more →Creative Chess
What makes a chess idea creative? AlphaZero db, a league of superhuman players that think in different ways, and PuzzleGen, which composes original puzzles that grandmasters called beautiful.
Read more →Rewards are Gradients
A general theory of what an RL agent can be asked to do. When the goal is a convex function of the states an agent visits — exploration, imitation, diversity, constraints — the reward that solves it is the gradient of that objective.
Read more →LLMs can't jump
A position paper examining a fundamental limitation of large language models: their difficulty with abductive reasoning, a capacity central to genuine scientific invention.
Read more →